What is Direct Memory Access (DMA)?
Direct Memory Access (DMA) is a hardware mechanism that moves data between memory and peripherals with minimal CPU involvement. The CPU still manages the DMA (configuring addresses, sizes, modes, and permissions), but the DMA engine performs bulk transfers over the system interconnect.
For an electronics engineer, the most useful mental model is: DMA is a bus master (or bus client with a given master capability) that can read/write memory and peripheral registers/FIFOs under strict rules defined by software. In a well-designed system, DMA increases throughput, reduces latency jitter, and frees up the CPU for control and signal processing work.
Why DMA Introduced in Computer Systems?
DMA exists because CPU-driven I/O is structurally wasteful:
- The CPU copy loop burns cycles, creates cache pressure, and increases interrupt frequency.
- Peripheral interfaces (ADC, SPI, SDIO, Ethernet MAC, USB, PCIe endpoints) generate/consume data faster than the CPU can efficiently maintain it.
- Real-time systems require predictable timing; heavy polling or frequent interruptions can throw off deadlines.
DMA addresses this by offloading “data movement” to dedicated hardware and letting the CPU focus on scheduling, protocol handling, and application logic.
How DMA Works Step by Step?
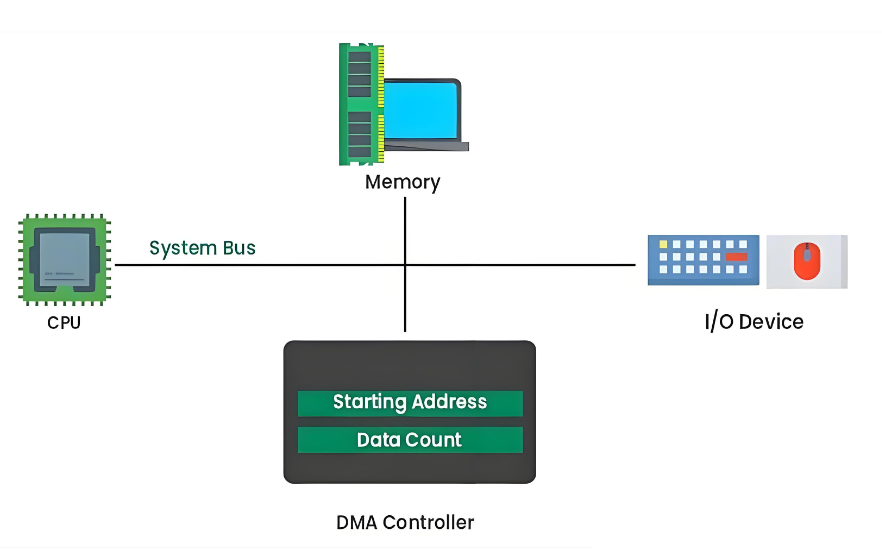
A typical transfer (microcontroller or SoC) looks like this:
1. Allocate buffers in RAM and define ownership rules (who writes, who reads, when).
2. Program the DMA channel: source address, destination address, transfer length, width, burst size, increment mode, and trigger source (timer, peripheral request line, or software trigger).
3. Enable/enable DMA and peripherals (e.g. enable UART RX DMA, start ADC, enable SPI TX DMA).
4. DMA performs arbitration for the bus, then performs sequential reading/writing.
5. Completion of DMA signals via interrupts, event flags, or callbacks; optionally, it can trigger a half-transfer event for the stream.
6. Software post-processes data (packet parsing, filter samples, buffer enqueue) and re-arms DMA if necessary.
If you’re designing embedded firmware, the real craft isn’t the registers that write; they are buffer lifecycle, coherence, and error handling.
What is DMA used for?
DMA is used whenever data volume, speed, or determinism makes CPU-driven transfers inefficient. It is widely used in:
- ADC sampling into a circular buffer for DSP, FFT, or control loop
- Continuous UART/SPI/I²C RX/TX without interrupt byte by byte
- I²S/SAI audio streaming with ping-pong buffer
- Storage blocks (SDMMC, NAND, QSPI) move to RAM
- Network Descriptor (Ethernet MAC) RX/TX rings
- Pipeline frame buffer retrieval (LCD/DSI).
- FPGA or high-speed sensor capture that prioritizes continuous bandwidth
Practical heuristic: if you handle continuous streams above a few tens of kB/s (depending on the platform) or you need tight jitter limits, DMA is usually worth it.
What are the three types of DMA?
These three “types” are commonly taught because they map well to bus usage and CPU impact.
DMA takes the bus and transfers one block (or burst) with minimal interruption. Throughput is high, but the CPU and other masters may stall or delay depending on arbitration priority.
DMA transfers one unit (or small burst), then releases the bus, inserting a CPU cycle. This increases responsiveness at the expense of peak throughput.
DMA transfers only when the CPU is not using the bus (or during “idle slots”). This minimizes CPU interference but can hinder transfers if the CPU is busy.
DMA vs CPU Based Data Transfer
When the CPU handles data transfer directly, it must read and write each unit of data. This process consumes clock cycles and reduces overall system efficiency.
DMA removes this bottleneck by enabling parallel operations. While the DMA controller moves data, the CPU continues to perform other tasks, increasing throughput and multitasking capabilities. Here is a detailed comparison between the two:
| Dimensions | CPU Copy | DMA |
| CPU utilization | Tall | Low–Medium (setting + ISR) |
| Peak throughput | Limited by CPU + bus | Mostly limited by bus + DMA |
| Jitter in real-time tasks | Often worse | Often better (if designed correctly) |
| Complexity | Low | Medium–High |
| Failure mode | Clear | Subtlety (alignment, coherence, ownership) |
Main Components of a DMA Controller
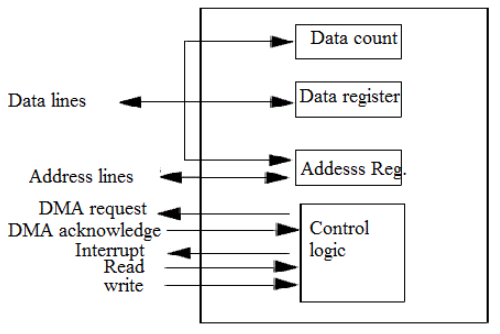
Most DMA implementations (MCU or SoC) contain:
- Channel/stream: independent transfer machine (or time slicing machine)
- Request routing: connects peripheral request lines to channels
- Address generator: addition/fixed addressing, wrap/circular mode
- Displacement size: byte/half word/word, burst length
- Descriptors/LLI (linked list): scatter-gatherer, chain transfer
- Status/interrupt logic: half transfer, complete, error, FIFO threshold
- Arbitration/QoS: priority levels, bandwidth limits, fairness rules
On high-end SoCs, DMA is often divided into special blocks: PDMA (peripheral DMA), XDMA (general), GPDMA, MDMA, or special engines for Ethernet, USB and displays.
DMA in Embedded Systems and Microcontrollers
DMA is a staple in embedded design because it converts “interrupts-per-byte” to “interrupts-per-buffer.”
1) Circular buffer for streaming
A common pattern is a circular DMA into a ring buffer, with half-transfer and full-transfer interrupts:
- ISR half transfer: processes the first half while DMA fills the second half
- Full transfer ISR: processes the second half while DMA wraps the first half
This provides stable throughput and predictable CPU load.
2) Ping-pong buffer
For traffic spikes or tight processing windows (audio frames, sensor blocks), use two buffers:
- DMA fills Buffer A while the CPU processes Buffer B
- Swap when finished
Ping-pong is often easier to validate compared to large hoops, especially when you have to guarantee “no overwriting before consumption.”
3) UART RX DMA for powerful logging and protocols
UARTs are notorious for their ISR overhead at high baud rates. RX DMA into a ring buffer plus “IDLE line” interrupt (common in many MCUs) is a powerful combination:
- DMA continuously writes bytes
- IDLE interrupts fire when the line stops
- The CPU reads the DMA write pointer and parses the frame
Practical guide: treat your DMA write index as the source of truth; avoid “guessing” the number of bytes.
DMA in Modern Operating Systems
In modern OS environments, DMA is not optional—it is fundamental.
Descriptor ringing and zero copy path
Network drivers, NVMe, and many high-speed devices are used descriptor ring:
- Driver post buffer descriptor (physical address, length, flags)
- DMA device-writes the received data directly to a buffer
- The driver then hands off the buffer to the stack or application
The most critical path to performance is goals zero-copywhere data is not copied again in the software unless necessary.
IOMMU and protection
On a PC/server, the device can DMA into memory. To control it safely, the platform uses IOMUM (Intel VT-d / AMD-Vi style conceptually):
- It maps addresses visible to the device to physical memory
- This prevents the device from reading/writing arbitrary DMA memory
- This enables secure virtualization and isolation
As an engineer, the important takeaway is: DMA is strong enough to be a security boundary, so modern systems limit it with translation and hardware permissions.
Advantages of DMA
- Lowers CPU overhead and reduces interrupt stress
- Higher sustained throughput for streaming I/O
- Better timing stability for control loops and real-time workloads
- Enables architectures such as descriptor rings and pipeline processing
DMA limitations
- Cache coherence: The CPU cache may not match the RAM contents that the DMA reads/writes
- Alignment and width constraints: some DMA engines require aligned addresses or a certain transfer width
- Buffer ownership bug: CPU modifies buffer while DMA is still using it
- Bus contention: DMA can starve other masters or cause latency spikes
- Error visibility: configuration errors can fail silently until a timeout occurs
DMA makes data movement fast, but makes system justification a discipline.
FAQs
1. Is DMA always faster than CPU copying?
Often yes to continuous transfers, but not universally. For very small copies, the CPU may be faster due to setup overhead. The crossover point depends on bus speed, DMA engine capabilities, cache behavior, and interrupt frequency.
2. What are the most common DMA bugs in embedded projects?
Cache coherence and buffer ownership. Engineers often forget to flush/invalidate caches (on systems with data caches) or accidentally reuse buffers before DMA completes.
3. Does the microcontroller also suffer from cache coherency problems?
Some do, some don’t. Many MCUs lack data cache, making coherence simpler. Higher-performance MCUs and SoCs often include cache, so coherency is a first-class design concern.
4. What is scatter-collector DMA and why do engineers use it?
Scatter-collector DMA uses linked descriptors to move non-contiguous memory segments without CPU intervention. This is important for networking, storage, and any system that uses buffer chains efficiently.
5. How to decide between circular DMA and ping-pong buffer?
Use circular DMA for continuous streaming where you can tolerate ringing semantics and want minimal reconfiguration. Use ping-pong when you need strict “block-by-block” processing with clear ownership boundaries.
6. Can DMA damage memory?
Yes, if the configuration is wrong or the address limits are wrong. That’s why strong drivers validate length, alignment, region permissions, and use memory protection when available.
7. Does DMA bypass the CPU for security reasons?
In many architectures, DMA can access memory without the CPU performing load/store. That’s why platforms use IOMMU-like controls, MPU regions, or DMA address filters to limit what DMA can touch.
Tag: DMA Direct Memory Access, DMA Types
This entry was posted on Monday, January 5, 2026 at 18:36 and is filed under best PCB, best PCB, FAQ. You can follow any responses to this entry via the RSS 2.0 feed. You can skip to the end and leave a response. Ping is currently not allowed.
Agen Togel Terpercaya
Bandar Togel
Sabung Ayam Online
Berita Terkini
Artikel Terbaru
Berita Terbaru
Penerbangan
Berita Politik
Berita Politik
Software
Software Download
Download Aplikasi
Berita Terkini
News
Jasa PBN
Jasa Artikel
News
Breaking News
Berita